Contents
Hero
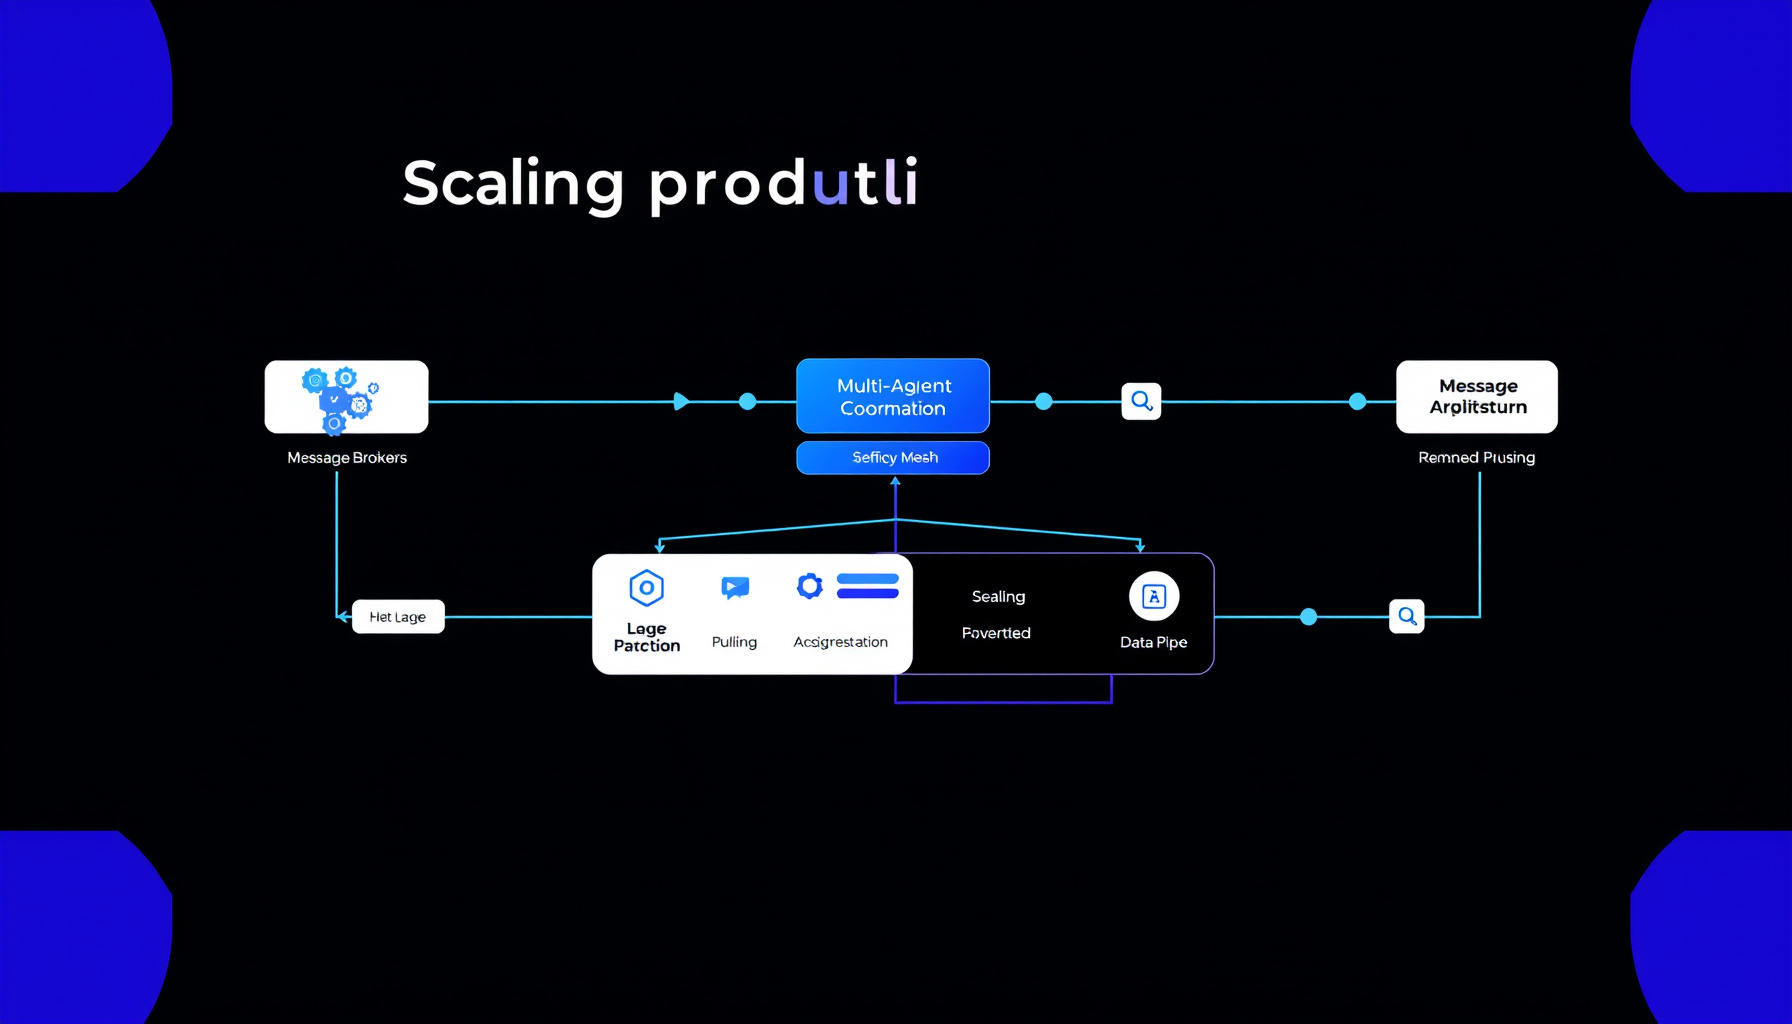
Scaling AI systems from prototype to production demands architectural patterns that balance performance, reliability, and cost. As workloads grow, traditional monolithic architectures hit limits in latency, throughput, and fault tolerance. This post explores production-grade patterns for scaling AI systems, focusing on deployment topologies, multi-agent coordination, and event-driven architectures.
Technical Deep-Dive
Deployment Topologies
Microservices with Agent Pools
For large-scale AI systems, microservices with dedicated agent pools offer horizontal scalability. Each agent pool specializes in a specific task (e.g., retrieval, generation) and scales independently.
# Example: Agent pool deployment in Kubernetes
from kubernetes import client, config

def deploy_agent_pool(namespace: str, pool_name: str, replicas: int):
    config.load_kube_config()
    api = client.AppsV1Api()

    deployment = client.V1Deployment(
        metadata=client.V1ObjectMeta(name=f"agent-{pool_name}"),
        spec=client.V1DeploymentSpec(
            replicas=replicas,
            selector={"matchLabels": {"app": "agent", "pool": pool_name}},
            template=client.V1PodTemplateSpec(
                metadata=client.V1ObjectMeta(labels={"app": "agent", "pool": pool_name}),
                spec=client.V1PodSpec(containers=[{
                    "name": "agent",
                    "image": "ai-agent:latest",
                    "env": [{"name": "AGENT_POOL", "value": pool_name}]
                }])
            )
        )
    )
    api.create_namespaced_deployment(namespace=namespace, body=deployment)
Serverless Edge Deployment
For low-latency requirements, serverless edge deployment leverages cloud providers’ edge networks. This reduces latency by placing inference closer to users.
# Example: Deploying a serverless function on AWS Lambda
aws lambda create-function \
    --function-name edge-inference \
    --runtime python3.9 \
    --handler inference.handler \
    --role arn:aws:iam::123456789012:role/lambda-edge \
    --zip-file fileb://function.zip \
    --publish
Multi-Agent Coordination
Event-Driven Architecture
Multi-agent systems benefit from event-driven architectures, where agents communicate via asynchronous events. This decouples components and improves scalability.
# Example: Event-driven architecture using NATS
version: '3'
services:
  nats:
    image: nats:latest
    ports:
      - "4222:4222"
    command: "--cluster_name NATS --http_port 8222"

  agent1:
    image: ai-agent:latest
    environment:
      - NATS_URL=nats://nats:4222
      - SUBJECT=agent1.requests

  agent2:
    image: ai-agent:latest
    environment:
      - NATS_URL=nats://nats:4222
      - SUBJECT=agent2.requests
Scaling Strategies
Horizontal Pod Autoscaling
Kubernetes HPA dynamically adjusts the number of pods based on CPU/memory usage. For AI workloads, custom metrics (e.g., request latency) can trigger scaling.
# Example: Custom HPA for AI inference
from kubernetes import client, config

def setup_hpa(namespace: str, deployment_name: str):
    config.load_kube_config()
    api = client.AutoscalingV2Api()

    hpa = client.V2HorizontalPodAutoscaler(
        metadata=client.V1ObjectMeta(name=f"{deployment_name}-hpa"),
        spec=client.V2HorizontalPodAutoscalerSpec(
            scale_target_ref=client.V1CrossVersionObjectReference(
                kind="Deployment",
                name=deployment_name,
                api_version="apps/v1"
            ),
            min_replicas=2,
            max_replicas=10,
            metrics=[{
                "type": "Resource",
                "resource": {
                    "name": "cpu",
                    "target": {
                        "type": "Utilization",
                        "average_utilization": 70
                    }
                }
            }]
        )
    )
    api.create_namespaced_horizontal_pod_autoscaler(namespace=namespace, body=hpa)
Tradeoffs & Alternatives
| Pattern | Pros | Cons | Best For |
|---|---|---|---|
| Microservices | Scalability, isolation | Complexity, network overhead | Large-scale, multi-team systems |
| Serverless Edge | Low latency, auto-scaling | Cold starts, vendor lock-in | Global, latency-sensitive workloads |
| Event-Driven | Decoupling, scalability | Debugging complexity | High-throughput, async workflows |
| Monolithic AI Service | Simplicity, low latency | Scaling limits | Small-scale, low-traffic systems |
Decision Framework
- Latency Requirements: Edge deployment for <50ms latency; serverless for <100ms.
- Team Structure: Microservices for distributed teams; monolithic for small teams.
- Traffic Patterns: Event-driven for bursty workloads; HPA for steady-state.
- Cost Sensitivity: Serverless for variable workloads; dedicated for predictable loads.
References
📖 Related Reads
- NiteAgent — AI agent development, frameworks, and production patterns
- ToolBrain — tool reviews, LLM comparisons, and AI workflow guides
🏆 Arena Match This post was generated by a 5-model arena competition. Winner and scores will be added after judging.
📖 Related Reads
- ToolBrain — tool reviews, LLM comparisons, and AI workflow guides
- NiteAgent — AI agent development, frameworks, and production patterns
Cross-links automatically generated from CodeIntel Log.